Stop Making Neural Networks Pretend to Be Programs
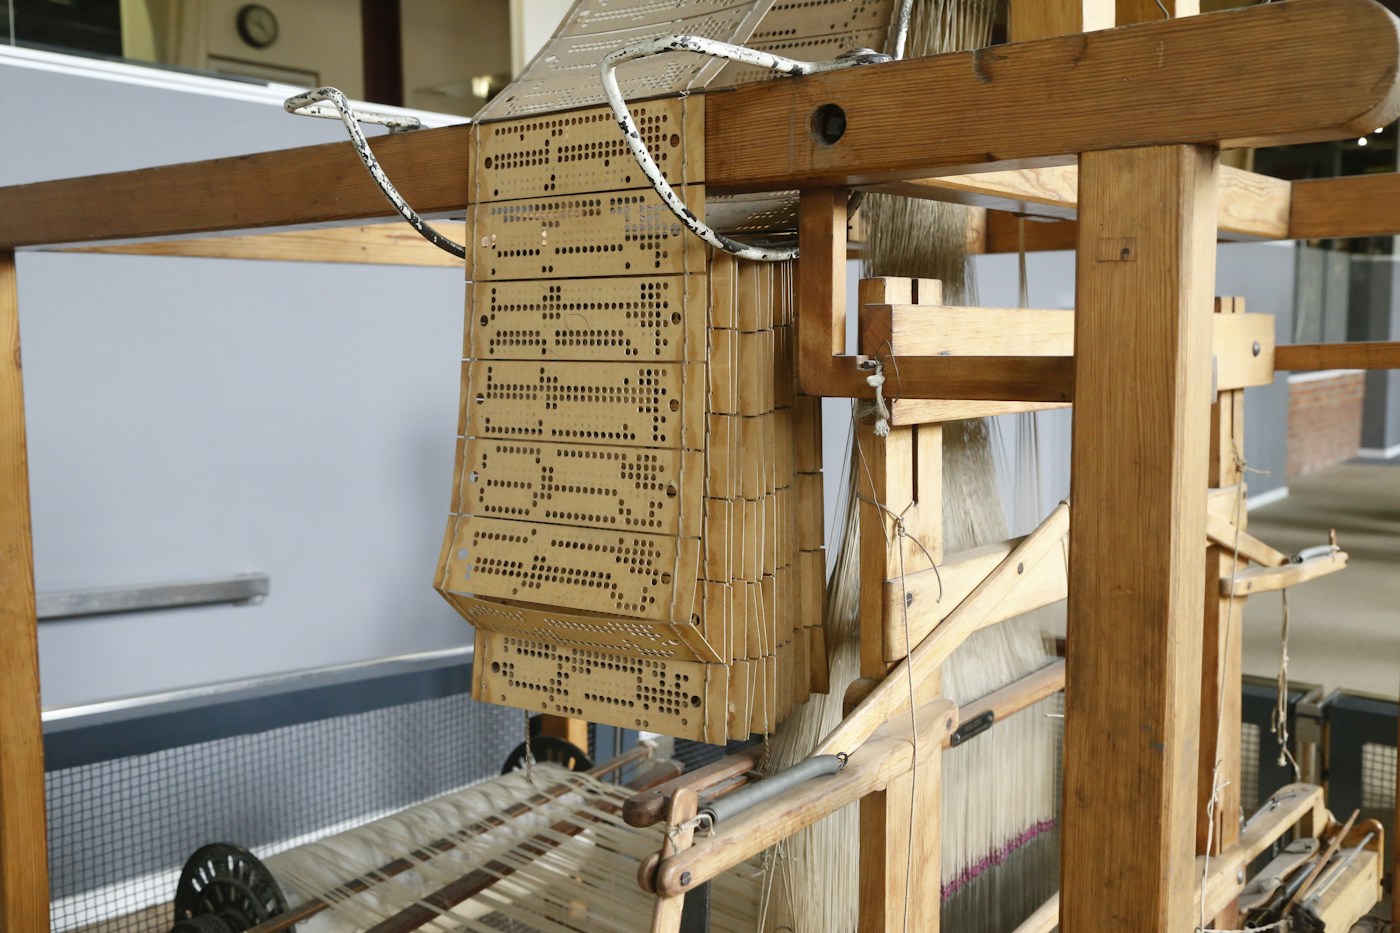
We may say most aptly that the Analytical Engine weaves algebraical patterns just as the Jacquard-loom weaves flowers and leaves.
– Ada Lovelace, notes on the Analytical Engine, 1843
Like many, I started in NLP from a deep fascination with both AI and human languages. Different languages are written, voiced, and used so differently across the world, yet they can express similar ideas, and AI can help bridge the barrier via machine translation. Underlying this is a satisfying phenomenon linguists call grammatical structure. Take a simple sentence and its Japanese translation:
The two languages order their words quite differently. English puts the verb before both of its objects (it is a subject–verb–object language, and the subject here is an implied “you”), while Japanese saves the verb for the very end (subject–object–verb), marking the direct object with the particle を and the indirect object with に rather than by their positions. Yet both put the adjective in front of the noun it describes: a better place, より良い場所.
What I find most satisfying about this structure is that compositionality falls right out of it: the meaning of a sentence is built from the meanings of its parts and the way those parts are put together. You have never seen most of the sentences you will read today (this one included, I hope), and yet you understand them without breaking a sweat, because you know the pieces and you know the rules for putting them together. To see it at work, replace the adjective with an entire clause:
In this case, Japanese puts the adjectival clause before the noun it modifies, just as it did the adjective, while English puts it after “place”, as a relative clause. Underneath, though, almost nothing has changed. In a Universal Dependencies analysis (a way of annotating grammar consistently across human languages), there is still exactly one modifier hanging off “place”, in exactly the slot “better” occupied, and most of the other words line up one-to-one across the two languages (hover over them below, or tap them on your phone, to see how).
Hover over or tap a word or an arc to see its counterpart in the other sentence.
To a young researcher, this suggested an obvious plan. If I could just have a function that translates a blob of meaning, such as that clause, as a whole unit, I could apply it recursively: translate the pieces, plug each one back into its slot in the tree, and the rest of the translation would never need to know that anything had changed. So one of my first NLP projects did exactly that with tree-shaped recursive neural networks, which follow a sentence’s syntactic tree and compose the meaning of each phrase from the meanings of its children. Learn the parts and the rules for combining them, and the endless combinations come for free. (That “just”, as it turned out, was hiding most of the hard part.)
Fixing the trees first
In practice, the idea worked a lot less well than the picture suggests. The trees we could produce automatically were not reliable enough, and a tree-shaped model builds everything on top of the tree it is handed: get one attachment wrong, and every phrase above it is composed from the wrong pieces. In the meantime, sequence models with attention were improving at a remarkable clip, without asking anyone for a tree.
So I took what I thought would be a short detour. If the trees were not good enough, perhaps I should work on the trees. (Anyone who has done research will know that there is no such thing as a short detour.)
The detour turned out to be a lot of fun. I got to explore the world of transition-based dependency parsing and propose a new transition system of my own, Arc-swift, and with Tim Dozat, Yuhao Zhang, Yuhui Zhang, Jason Bolton and Chris Manning, we had fun designing how a single, data-driven system could process and parse 66 human languages with almost no language-specific design, first for the CoNLL shared tasks and then in Stanza.
Parsing also taught me that structure is useful well beyond translation. In relation extraction, the words that matter tend to sit on the dependency path between the two entities, and Yuhao, Chris and I found that a graph convolutional network over the tree, pruned to the neighborhood of that path, worked remarkably well.
The tree cuts past the five words about where Alice Chen grew up, straight to “Alice Chen ← worked → Acme”, and the one word just off that path tells you that she never did. Structure like this turned out to give powerful pre-trained Transformers a boost as well, as long as the parses came from human annotators. That last caveat stuck with me. Symbolic structure is powerful when it is right, and only then. A tree from an unreliable parser can hurt just as easily as it helps. Hold on to that thought; it will come back.
Reading, searching, and knowing when to stop
Back in 2018, while I was still busy with trees, neural models were getting good, and getting good fast, and I found structure in question answering, too, only at a coarser grain: answering a complex question often takes a chain of reasoning steps, each one building on what the previous one found. The traditional route would have been to extract relations into a knowledge base and query it, which fixes the structure ahead of time and only covers the relations someone thought to extract. We wanted instead to embrace neural models for generic semantic inference over raw text, and to keep the structure in the reasoning steps themselves. The problems this let us take on began to look a lot like what we now call agents.
That year, a dinner conversation with my FAIR co-interns Zhilin Yang and Saizheng Zhang turned into HotpotQA, a dataset of questions that can only be answered by reasoning over more than one Wikipedia article. Here is an example: “What government position was held by the woman who portrayed Corliss Archer in the film Kiss and Tell?” You first need to find out who played Corliss Archer (Shirley Temple) before you can look up the government position she held, and since the question never mentions Shirley Temple, searching with the question alone will not find the second article.
A year later, my follow-up GoldEn Retriever dropped the fixed retrieve-then-read script that most systems followed at the time. At each step, the model wrote its own search query from the question and whatever it had read so far, and our later IRRR system also decided for itself, question by question, whether it had read enough or needed another step. The loop itself was a fixed script, and the model filled in each step: what to search for next and, in IRRR, whether to stop. If you swap the search engine for any tool with an API, you get the loop at the heart of today’s tool-using agents: write the arguments of the next tool call, read what comes back, and decide whether to call another tool or to answer. Deep research systems run essentially this loop, with far more capable models and many more tools. (I have written separately about why HotpotQA alone is no longer a good way to evaluate those systems; eight years turns out to be a very long time in AI.)
x is never just x
And yet, one thing kept nagging at me, and it goes all the way back to compositionality.
In a symbolic system, a variable is just a slot. x + y = y + x holds whatever x and y happen to be, and if you rename x to z everywhere, nothing changes. A neural model cannot quite see it that way. It represents every token as a vector, and that vector is learned from how the token is used, so x and y are never really interchangeable slots to the model. Each comes with its own distributional baggage (x shows up in different contexts than y, in different textbooks, next to different words), and the identity of a variable ends up tangled with its meaning.
To make this concrete, I trained a simple two-layer network to complete A + B = B + ?, where each token is represented by a learned 3-dimensional vector. Almost all of the 4,000 training examples use English letters as variables, and only 15 throw in the Greek letter θ. The trained network runs in your browser below, so you can pick any two variables and see what it does.
θ wrong in three of them. A version trained on names instead ("Alice thanked Bob. Who thanked?") fails on a rarely seen name in the same way, though less consistently (two runs out of four).The reason is that neural models are, at heart, distributional models. They learn what tends to go with what in the data they were trained on. That is enormously powerful, and it is exactly why they can handle the messy, open-ended inputs that symbolic systems never could. But it also means that when an input is rare, or changes in a way that should not matter, the model’s priors can override what is right in front of it.
We keep running into this in our own work. Vision-language models will confidently tell you that a five-legged dog has four legs: on the VLMBias benchmark, GPT-5.2 scores 4.6% and Claude Sonnet 4.6 scores 0%. With Yijin Ni and Simon Yu, we found that training the model to also ask which prompt best explains a response, an idea we call abductive preference learning, raises the accuracy of the model we trained from 3% to 44% there. And in work with Artin Tajdini and Manpreet Kaur (under review), we found that simply renaming a tool, or offering an equivalent one, can make a trained agent much worse at a task that has not changed at all, unless it is trained to act consistently across equivalent interfaces.
Others saw the same thing well before agents were in fashion, on question answering over Wikipedia. Models were easily thrown off by a single distracting sentence added to a paragraph from SQuAD, the Stanford Question Answering Dataset, struggled to tell when a question had no answer in the passage at all, and often answered from memory when the answer in the passage was swapped for a different one. More recently, GSM-Symbolic showed that changing only the names and numbers in grade-school math problems lowers model accuracy, and in 2025 a popular AI search assistant insisted that 1995 was not 30 years ago, and at times called it both 29 and 30 years ago in a single answer. To us, a tool name or the name of a person in a word problem is just a symbol, but to the model it is also a distributional cue.
Fixes like abductive preference learning and consistency training across interfaces are worth doing, and they work. But each of them either widens the distribution the model sees, or regularizes the model to behave more consistently across it. None of them actually makes x a variable.
Islands of code
In agents, the closest thing I had seen to making x a variable was skill induction, where the agent writes reusable code subroutines from its own experience and calls them later (Voyager, Agent Workflow Memory, ASI and SkillWeaver, to name a few). With Simon Yu, Gang Li and Weiyan Shi, we built PolySkill, which borrows polymorphism from software engineering to separate a skill’s abstract goal from its site-specific implementation. That made skills reused far more often, and made the agent noticeably better on websites it had never seen.
Skills are real progress, because inside a skill, x finally is a variable. But skills are islands of code in a neural sea. The model still decides which skill to call, in what order and with which arguments, and it still has to remember where it is in the plan. The top-level control flow, which is precisely where long tasks tend to go wrong, is still neural.
I find it helpful to think about this the way we think about quantum computers. We can simulate a quantum computer with a classical one, and for small problems people do, but nobody plans to do the real work of quantum computing that way, because the simulation is vastly more expensive than the thing it imitates. It stands to reason, then, that we should not be forcing neural models to simulate the programmatic behavior that code is already built to do. Yet that is what an agent is doing when it keeps a loop counter in its context window, reminds itself which of fifty records it is on, or re-derives the same procedure for the thousandth time: running an expensive, approximate simulation of a for loop, on hardware that was built for something else entirely.
For a long time, I did not have an answer to this that I was happy with — until now.
Letting the program be the agent
Recently, some wonderful collaborators and I worked on a project called Agent Behavior as Code, or ABCAgent for short, whose central idea fits in one sentence: the agent’s behavior is fully specified by a program, and the neural model’s job is to write and edit that program.
Code stops being something the model occasionally reaches for and becomes the central, persistent artifact. A capable model, which we call the Designer, writes a Python program for a task, and a symbolic executor (here, simply a Python interpreter) runs it. The program can call neural functions for the steps that resist code, such as reading a messy web page or judging whether an answer is plausible, and it can even call the whole agent recursively for a sub-problem. When the program fails, or the requirements change, the Designer edits it.
It helps here to separate two activities that today’s agents blur together. Agent design is everything that changes how the agent behaves, such as an example, a correction or a new rule, while agent execution is the agent doing the work on a given input. When both happen in the same context window, as on the left of the figure below, the example’s values can leak into the next task (the x-and-y problem again, only at the level of a whole task), a rule added in chat may or may not be followed, and the window grows with every step.
llm().The first of these problems is not even new. Classical AI ran into it decades ago, and explanation-based generalization was an answer to it: replace the constants of a worked example with variables, and you get a solution you can reuse. The difference now is that we finally have models capable enough to do that generalizing for us, in a general-purpose programming language, on arbitrary tasks.
Concretely, an ABCAgent program declares, up front, the parameters it can be re-bound on: the values that a particular task supplies, kept apart from the logic that consumes them. When a new task arrives, ABCAgent first checks whether a stored program for that family of tasks fits. If it does, a couple of lightweight model calls map the new task’s values onto the program’s parameters and check the result, and the program runs. No new code is written, and there is no agent loop. If no program fits, or rebinding fails, the Designer writes or edits one in a fairly standard code-generation loop with execution feedback. Two checks then decide what gets stored. The first is a variant check: the Designer proposes variants of the task at hand, and the program has to handle them, changing its behavior when a parameter changes. This weeds out programs that are general only in their parameter block, and since it needs no labeled answers (much like metamorphic testing), it works in production, too. The second is a no-regression rule: when a stored program is edited for a new task, the edit must still solve every task the program solved before.
This is where the lesson from my parsing days comes back. A tree from a bad parser hurts, and a program that only looks general hurts just as much, with the added insult that it repeats its mistake on every input it sees. The variant check is how ABCAgent decides which programs deserve our trust.
The tree, again
Here are two real programs that ABCAgent wrote, taken from our runs. The first is for a GSM-Symbolic problem, where all fifty instances of the problem family share one derivation and only the constants differ; the second shows what it looks like when rebinding goes wrong.
(a) A stored program, rebound to a sibling task
"""
Variants this script handles by changing
parameters in Section A:
 - Variant 1: 8 remoras instead of 7
     -> set NUM_REMORAS = 8
 - Variant 2: 84-inch remoras instead of 72
     -> set REMORA_LENGTH_INCHES = 84
"""
# Section A - parameters
WHALE_LENGTH_FEET    = 10   # sibling i39: 80
NUM_REMORAS          = 8
REMORA_LENGTH_INCHES = 3    # sibling i39: 30
# Section B - derivation (byte-identical
# across all 50 instances of this family)
combined_inches = (NUM_REMORAS
                   * REMORA_LENGTH_INCHES)
combined_feet   = combined_inches / 12
result = (combined_feet
          / WHALE_LENGTH_FEET) * 100
if result == int(result):
    result = int(result)
print(f"<final_answer>{result}</final_answer>")
(b) A rebinding that fails, visibly
'''
Variants this script handles by changing
parameters in Section A:
 - As-is (this task): Find the SECOND
     longest word on board ABRL/EITE/IONS/FPEI
 - Variant 2: Find the longest word
     (first tier) -> set LENGTH_RANK = 1
'''
BOARD_STRING = "ABRLEITEIONSFPEI"
LENGTH_RANK  = 1   # task asks for the SECOND
Look at Sections A and B in panel (a). Section B is the “tree” (problem structure), and Section A holds the slots. Solving a sibling task means translating its values and plugging them back in, which is exactly the move I wanted to make with “a place where humankind and nature coexist in harmony”, more than a decade ago. The difference is that this time, the structure does not come from an unreliable parser. It is written by a capable model, and checked by execution before anyone trusts it.
And when things do go wrong, as in panel (b), the failure is legible. The whole error is one wrong integer in the parameter block, and you can spot it without running anything. A purely neural agent leaves no such artifact behind: when it gets a task wrong, there is no line of code to point at.
Neuro-symbolic, but which kind?
Henry Kautz’s taxonomy of neuro-symbolic AI gives a useful vocabulary for what is going on here. Symbolic[Neuro] is a symbolic program that calls neural components, like AlphaGo’s tree search over a neural value function. Neuro[Symbolic] is a neural system that calls symbolic tools, like a language model invoking a calculator or a theorem prover. Almost every LLM agent today is Neuro[Symbolic]. CodeAct-style agents emit code snippets as actions and throw them away afterwards, and skill-based agents call stored subroutines, but in both cases the model sits on the outside and runs the show.
ABCAgent is a third arrangement, which we write as a recursive definition, NS = Neural[Symbolic[NS]]. The outer Neural is the Designer, which writes and edits programs; Symbolic is the program and its executor; and inside the program, any step can call a neural function, or a fresh copy of the whole NS system for a sub-problem.
Gary Marcus has argued that coding agents like Claude Code are already neuro-symbolic, since their harnesses contain a great deal of conditional logic. I think he is right, but there is a difference that matters a lot. However it gets written (and much of Claude Code is, in fact, written by Claude Code), a harness like that is generic: the same code serves every coding task it was designed for, and the model still decides what to do at each step. It does not rebind a program to a new task, evolve its behavior one family of tasks at a time, or optimize away the model calls a task does not need. In ABCAgent, the symbolic half is the behavior itself, written for one family of tasks at a time and revised as the family grows.
One consequence I find especially satisfying is what happens to memory. In a neural agent, state is text in the context window (“we previously established that the account number is 4417”). In ABCAgent, state is a variable, account = 4417, with a value and a type, and no interpretation required. Execution progress is not a transcript but a call stack: when the program enters a loop, the executor, not the model, knows that it is on record 37 of 100, and the program, not the model, decides what carries over from one record to the next, so nothing leaks between records by accident. We saw a version of this on WorkArena-CF, a version of the WorkArena benchmark of enterprise web tasks that we rebuilt with loops and branches. At a hundred records, ABCAgent used 35% fewer tokens than a strong neural baseline (more on the experiments below) and wrote 51.5% of records correctly, against 39.3%. Its errors also were not the kind that pile up record by record: almost all of them came from a single mistake in the program, replayed on every record that needed that field. That is a much better kind of error to have, because you can find it once and fix it once.
What the experiments say
We evaluated ABCAgent on six benchmarks, two of which we built to test how well a program generalizes to variants of the task it was written for: augmented GAIA, with parametric variants of GAIA questions, and WorkArena-CF, which composes enterprise web tasks into loops and branches. The baseline is a strong neural agent on a Claude Code-style harness (on τ²-bench, the benchmark’s own stock agent), and both systems use the same model, Claude Sonnet 4.6. In the table, the first two columns are success rates (on τ²-bench, Pass4, the rate at which all four repeated trials of a conversation succeed), and cost efficiency and speedup are the neural agent’s cost and model-call time divided by ABCAgent’s, so values above 1× favor ABCAgent. (By wall-clock time, which also counts running the programs and checking them, ABCAgent is actually slower on both GAIA sets.)
| Benchmark | Neural agent | ABCAgent | p-value | Cost efficiency | Speedup |
|---|---|---|---|---|---|
| GAIA (165) | 76.4 | 72.7 | 0.38 | 0.90× | 0.85× |
| Augmented GAIA (378) | 59.5 | 57.1 | 0.28 | 1.24× | 1.33× |
| WorkArena L1 (31) | 84.9 | 62.4 | 0.04 | 0.41× | 0.36× |
| WorkArena-CF (42) | 58.3 | 64.3 | 0.45 | 1.02× | 0.92× |
| GSM-Symbolic (5000) | 97.3 | 98.3 | 0.001 | 6.97× | 5.21× |
| τ²-bench telecom, Pass4 (114) | 47.4 | 71.9 | 0.0001 | 12.93× | 9.50× |
| τ²-bench airline, Pass4 (50) | 58.0 | 60.0 | 1.00 | 5.66× | 4.08× |
On open-ended tasks like GAIA, writing the behavior down as a program costs little, if any, accuracy; ABCAgent is a few points lower, but not significantly so. Where tasks are regular or long, it helps. On the telecom domain of τ²-bench, the chance that all four repeated trials of a conversation succeed rises from 47.4% to 71.9%. Part of that is plain accuracy (a single trial succeeds 81.6% of the time, against 60.8%), but the program also loses less when it has to succeed four times in a row, which is what you would hope for from code.
The efficiency gains are large, and nearly all of them come from reuse. On augmented GAIA, a task that needs a new program costs ABCAgent about as much as it costs the neural agent ($1.61 against $1.59); the savings come from the tasks that do not. 92.6% of GSM-Symbolic tasks and 20.1% of augmented GAIA tasks are solved by rebinding an existing program, without writing any new code, and the cost efficiency rises with that share.
Reuse also buys something I care about more than cost, which is backward compatibility. Anyone who has retrained a model with extra data to fix a handful of failures knows how hard this is to manage: the targeted cases improve, while some test cases that used to pass regress, in ways that are difficult to predict and harder still to track down. Code is much easier to manage in this respect, because an edit either keeps the old test cases passing or it does not, and you can check before anything ships. Because every edit is checked against the tasks the program solved before, a stored program on augmented GAIA still solves 46.9% of the earlier tasks in its family, against 30.5% for programs written one task at a time. It also transfers better to tasks it has not seen, substantially on GSM-Symbolic but not measurably on augmented GAIA, where new variants often bring new requirements. The agent, then, forgets a lot less as it keeps learning, which is something that neither prompts nor fine-tuned weights reliably give you.
A few things surprised me along the way. Programs turned out to defer to the model only where a step resists code: 7.1% of stored GAIA programs hand some step back to a model, almost always through one generic, open-ended sub-call, while none of the 4,999 GSM-Symbolic programs do. Deep recursion is rare, too; the design lets a delegated step write a program of its own, but nesting beyond one level happened exactly once in all of our runs, though that may say more about our benchmarks than about the agent. The variant check also mattered more than I had expected. On WorkArena-CF, removing it was disastrous: replayed programs committed records with wrong field values, including one program that ignored its per-record input entirely and submitted the same values every time. Not a single record was correct, even though the run was cheaper. Finally, reuse only saves money when rebinding is cheap: without it, every task still goes through the authoring loop, just with more to read.
It does not work everywhere, either. On WorkArena L1, where every task is a one-off that never recurs, ABCAgent pays its authoring cost in full and gets nothing back, so it costs about 2.4× as much as the neural agent. It also succeeds less often there, mostly because its programs leave the browser on a page other than the one the benchmark checks (an order that never quite reaches its confirmation screen, for instance). And all of our results come from one model family on one harness, so how this changes across models, including smaller Designers, is still an open question.
Where I think this goes
From here on, I am going beyond what our experiments measure, so please read these as bets rather than results.
-
The marginal cost of an agent will decide where it gets used. At scale, most work recurs. A neural agent’s economics are those of a metered utility, where every run pays for a full round of reasoning, while a program’s are those of software, with a one-time design cost and a small cost per run. On τ²-bench telecom, where ABCAgent writes one program for the whole domain, that program paid for itself before we had run the benchmark one and a half times.
-
Agents will be mixed-model, and programs make the split clean. Once behavior is a program, what is left for the model at run time is small and narrow: bind these values, extract this field, judge this answer. On GSM-Symbolic, those calls cost $18.01 in total across 5,000 tasks. Narrow calls are where small, specialized models hold their own, as we saw even with neural agents in WARC-Bench, where an open model trained on short web subtasks outperformed many frontier computer-use models. I expect the frontier model to act more and more like a compiler, writing and repairing programs, while small models serve the
llm()calls inside them. -
Continual learning will happen in programs before it happens in weights. Fine-tuning on new data tends to erode old skills, and a prompt edit makes no promise either way, whereas a versioned program can grow through edits that are each checked against everything that worked before.
-
Neural models will be most valuable at the edges. Let them understand messy inputs, write and repair structure, and make judgment calls, and let code hold variables, run loops, keep state, and behave the same way every time. It is the division of labor I was reaching for with tree-shaped translation all those years ago.
-
The next discipline will be agent engineering. The broader technical reason is testability. You can test anything you can execute, but behavior that only exists in a model’s next decision can only be tested end to end, through integration tests and what you observe after rollout. Behavior that is written down can be decomposed and stress tested one component at a time, and it supports claims about generalization (“this program handles every value of this parameter”) that you can test by running it, and sometimes confirm just by reading it. In a few short years we went from prompt engineering to context engineering to harness engineering, each about tuning what the model reads or what surrounds it. I expect the next step to be agent engineering in the literal sense: behavior written as programs that models write, people review, and execution checks against variants and old tasks before anything ships. The craft moves from coaxing the right behavior out of a model on every run to deciding what it should be, once, and writing it down.
What would change my mind? The obvious candidate is models becoming so cheap and so reliable that re-deriving every behavior on every run costs next to nothing and never drifts. I do not expect that to happen, for the same reason we do not plan to do the real work of quantum computing on classical simulators. A neural model emulating a for loop spends billions of floating-point operations per token on what a processor does in a handful of instructions, and as models get cheaper, so do the few model calls a program still makes, so the ratio between the two stays put. Even a perfect model would also leave you with behavior you cannot diff, review, or sign off on. The more serious limits are the ones we measured: one-off tasks do not benefit, some families of tasks resist parameterization (when a variant changes how the answer has to be found rather than which values go in, no new constant will help), and we have not yet shown how all of this holds up across model families and with small Designers. That is where the next round of work is.
I should also say that this idea has good company. DSPy, 12-Factor Agents and Anthropic’s distinction between workflows and agents all push toward more code and less free-form prompting, and concurrent work such as LLM-as-Code also lets a program rather than the model govern an agent’s control flow. What I think is distinctive about ABCAgent is the combination: the model writes the entire behavior, the program declares its parameters, it is only stored after passing an executable check of its generality, and it is reused across a family of tasks under a no-regression check.
Final thoughts
When I tried to translate “Make the world a place where humankind and nature coexist in harmony” by plugging a clause into a tree, the idea was right, but the tools were not ready. The trees came from parsers that were too often wrong, and the model composing over them had no way of knowing.
The idea has not changed much since then, but we now have neural models good enough to write the structure themselves, in a language far more expressive than a parse tree, and execution to check that the structure is right before we trust it. The slot in the tree became a parameter in a program, and the clause that filled it became the values a new task supplies. Lovelace described the Analytical Engine as weaving algebraic patterns the way a Jacquard loom weaves flowers and leaves. I think good agents will work in much the same way: the pattern lives in the cards, a neural model is very good at punching them, and nobody needs to ask the weaver to hold the whole pattern in their head.
This post is based on Agent Behavior as Code: Efficient and Robust LLM Agents with Programmatic Specifications, joint work with Chunliang Lyu, Gang Li, Fabian Chan, Cheng Chang, Ignacio Cases and Will Lu, now on arXiv and currently under review. The tool-interface results are from separate work, also under review.
Enjoy Reading This Article?
Here are some more articles you might like to read next: